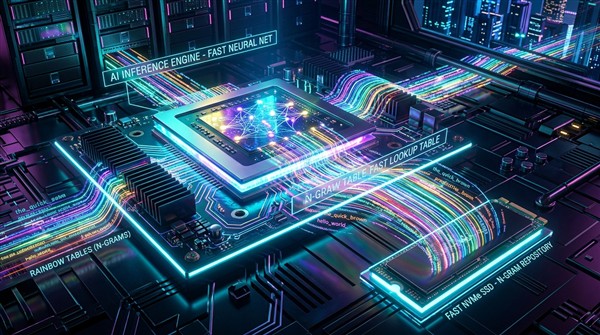
Getting 10 tok/s on Qwen 3.8 Flash Next: Why N-Gram Disk Paging Works Where MoE Fails Aug 28, 2026 How I got Qwen 3.8 Flash Next running at 10 tokens/sec on an RTX 5060 Ti, and why paging n-gram tables from NVMe avoids the brutal disk bandwidth bottlenecks of MoE expert streaming. Read More
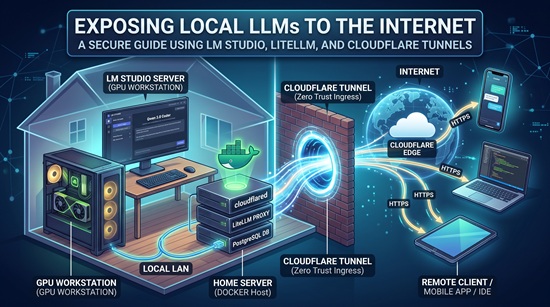
Exposing Local LLMs to the Internet with LM Studio, LiteLLM, and Cloudflare Tunnels Aug 16, 2026 How to securely publish local LM Studio models to the internet using a Dockerized LiteLLM proxy and Cloudflare Tunnels. Read More
Visualizing the Training of a Custom LLM May 12, 2026 A visual deep-dive into training a custom transformer LLM from scratch with PyTorch, analyzing loss curves, overfitting, and hyperparameter tuning. Read More
Running Clawbot on Local LLMs and Cloudflare Tunnels Feb 2, 2026 A hands-on setup guide for running Clawbot against local LM Studio models and securely exposing the web interface using Cloudflare Tunnels. Read More
Does Windows Dev Drive Actually Speed Up Local LLMs? A Deep Dive into ReFS, Defender, and NVMe Paging
 GaⅤin.com by Gavin W.