 GaⅤin.com by Gavin W.
Colibrì vs. FreeToken: Can Consumer Hardware Really Run Frontier MoE Models?
An empirical comparison of Colibri vs FreeToken for edge MoE serving, breaking down RAM limits, NVMe Direct DMA, the WSL2 I/O tax, and real tokens/sec.
An empirical comparison of Colibri vs FreeToken for edge MoE serving, breaking down RAM limits, NVMe Direct DMA, the WSL2 I/O tax, and real tokens/sec.
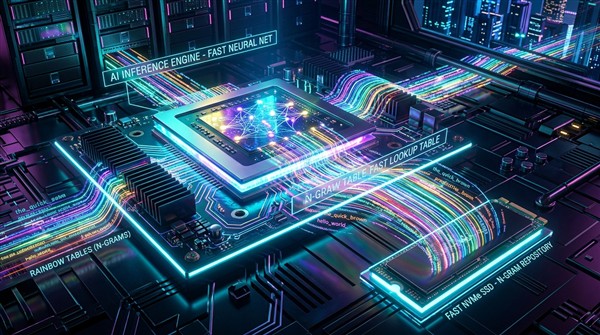
How I got Qwen 3.8 Flash Next running at 10 tokens/sec on an RTX 5060 Ti, and why paging n-gram tables from NVMe avoids the brutal disk bandwidth bottlenecks of MoE expert streaming.
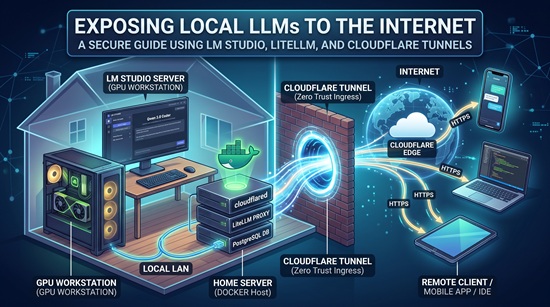
How to securely publish local LM Studio models to the internet using a Dockerized LiteLLM proxy and Cloudflare Tunnels.
Troubleshooting Blender startup crashes and "Not Enough Video Memory" errors caused by dual-monitor GPU display routing.
Colibrì vs. FreeToken: Can Consumer Hardware Really Run Frontier MoE Models?
 Does Windows Dev Drive Actually Speed Up Local LLMs? A Deep Dive into ReFS, Defender, and NVMe Paging
Getting 10 tok/s on Qwen 3.8 Flash Next: Why N-Gram Disk Paging Works Where MoE Fails
I love to hear from you!